data for language models
Model quality starts with data
We are a team of data engineers. We prepare the documents and data language models run on: corpora, datasets, structuring for RAG and fine-tuning.
why data
Quality starts long before the first prompt.
A model answers with exactly what is in its data. If documents are gathered without structure, with duplicates and junk — neither model choice nor prompts will help. We put documents and data in order beforethey reach your RAG system or training pipeline.
how we work
From raw documents — to ready data.
We collect and clean corpora, structure documents, annotate examples and check quality at every step. The output is production-ready data, with process documentation.
- Corpus and dataset collection and cleaning
- Chunking and metadata for RAG
- Example validation for fine-tuning
first step
Got documents or data that need preparing for an LLM?
Tell us what documents and data you have and what task they are being prepared for. We will propose a preparation plan and estimate the effort.
engagement formats
What we prepare for language models
Corpora and datasets
Documents for RAG
Data for fine-tuning
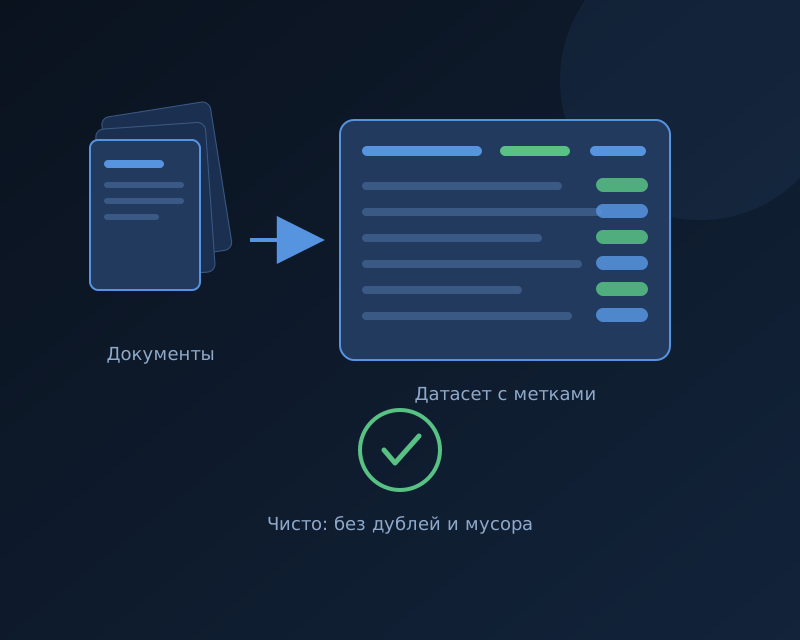
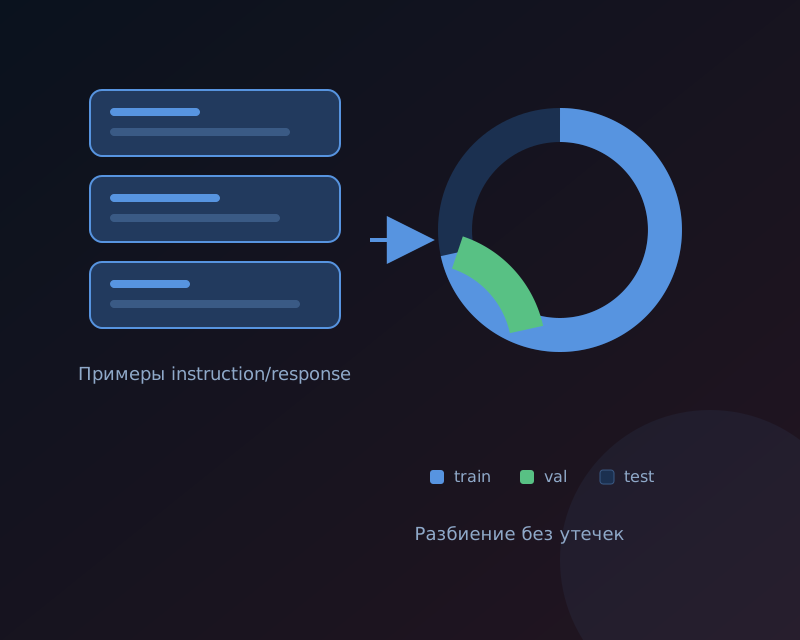
Corpora and datasets
We collect, clean and annotate text corpora and datasets for model training and fine-tuning tasks.
Documents for RAG
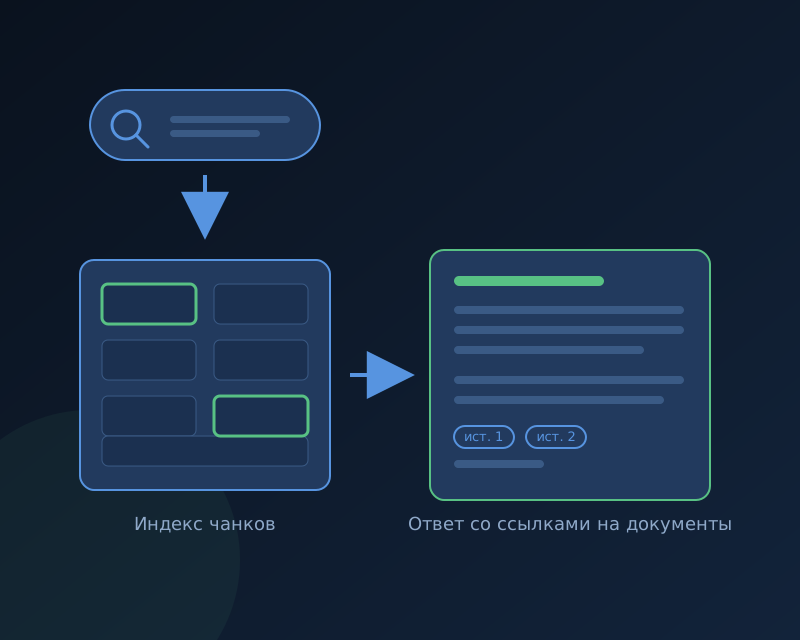
We structure documentation for retrieval-augmented generation: chunking, metadata, retrieval quality.
Fine-tuning preparation
Instruction and domain datasets for fine-tuning: formats, templates, example validation.
Data quality control
We check completeness, consistency and cleanliness: deduplication, quality metrics, sample audits.
Text extraction
We extract text from PDF, DOCX, HTML and scans: tables, structure — without losing meaning or adding junk.
Data readiness audit
We assess whether your data is fit for RAG or training and what to fix: an issue map and a preparation plan.
blog
Writing about data for LLMs — RAG, corpora, quality
Ready to discuss your task?
© Copyright 2026 AI Engineering